Choosing the Right Image Classification Algorithm
Image classification technologies have evolved from recognizing cats and dogs into the foundation upon which autonomous vehicles, medical diagnostics, and retail automation rely. As businesses and organizations increasingly depend on visual data to drive decision-making, the demand for accurate image classification algorithms continues to grow.
However, every development team inevitably faces a challenging question: how, out of hundreds of available solutions, do you select the specific algorithm that solves a concrete task without incurring unnecessary budget expenses?
Quick Take
- CNNs and modern pre-trained models are a common choice for classifying complex images.
- The quality and balance of the training dataset influence the outcome no less than the choice of model architecture.
- Transfer learning helps adapt an off-the-shelf model to a specific task without training from scratch.
- Testing on independent data allows for evaluating how well the model will perform on new images.
Core Image Classification Algorithms
Image classification is a computer vision task in which a model assigns one or several defined categories to an image. For instance, it can assign a photograph to a specific object identification class such as "car", "dog", or "bird".
Different algorithms are used for different tasks:
- Convolutional Neural Networks (CNNs). Convolutional neural networks learn to recognize visual features directly from images. They are suitable for complex tasks, including product classification, medical imagery, and satellite imagery. Well-known architectures include ResNet, EfficientNet, and MobileNet.
- Support Vector Machine (SVM). This algorithm finds the decision boundary between classes based on data features. It can be useful for small-to-medium-scale tasks, especially when visual features have already been extracted and prepared.
- Random Forest. This algorithm combines the outputs of multiple decision trees. It can be used for classification based on prepared features, particularly in tasks where evaluating the feature importance of different characteristics is critical.
- Pre-trained Models. Instead of training from scratch, a team can take a model that has already learned to recognize general visual features and adapt it to a specific dataset. This approach is called transfer learning. It frequently reduces training time and lowers the requirement for vast amounts of specialized data.
How to Select an Algorithm for a Specific Task
First and foremost, you need to define what exactly the model must recognize and under what operational conditions it will function.
1. Data volume and diversity. If the dataset is small, a pre-trained model may prove more practical than training from scratch. However, the sheer quantity of images does not guarantee quality: it is essential that they represent real-world deployment conditions.
2. Accuracy versus speed. For medical image analysis, a missed anomaly can be a significantly more severe error than a false positive. Conversely, for product sorting, processing speed and throughput stability across a massive data stream are sometimes more critical.
3. Computational resources. Large neural networks may demand powerful GPUs, additional memory, and extensive training time. If classification needs to run directly on a mobile device or a camera, a lightweight model may prove to be the more practical solution.
4. Scalability. If the data volume grows or categories evolve, the team must understand how to update the dataset, retrain the model, and monitor prediction quality.
The Role of Quality Data Annotation
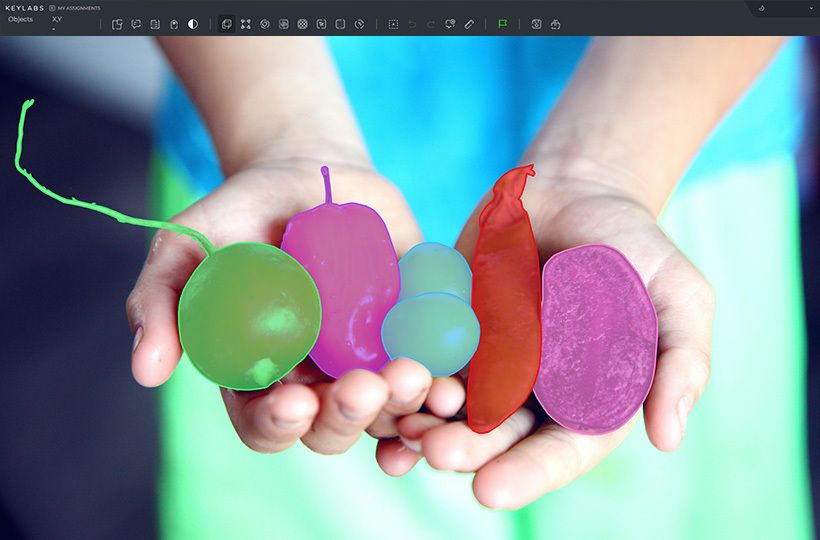
No neural network – no matter how advanced – will function effectively without high-quality "fuel": accurately labeled data. The annotation process for classification tasks consists of precisely assigning the correct labels to each image or image segment.
The algorithm learns from examples, so errors in training labels can lead to erroneous predictions. If photos of the same class are labeled inconsistently, or if key categories are underrepresented, the model may absorb incorrect patterns.
During annotation, images receive labels according to pre-defined categories. For instance, in retail, these might be product types; in agriculture, plant species or disease indicators; and in medical imaging, pathology categories defined per project criteria.
Before starting work, it is vital to align guidelines: what distinguishes one class from another, how to label ambiguous cases, and what to do if an image fits no category. This ensures different annotators apply identical rules.
Dedicated attention must be paid to quality control. Sample audits, re-annotation of complex examples, and discrepancy arbitration allow for spotting systematic errors before training begins. Class distribution should also be checked: if certain categories appear much more frequently than others, the model may become overly biased toward the most common class.
How to Evaluate Model Quality
After training, the model must be evaluated on data that was not used during its training phase. This helps clarify whether it can correctly classify new images. A single metric is insufficient for all tasks.
Popular Developer Mistakes
Even the most expensive neural networks fail due to basic design-stage errors:
- Overfitting. The model simply "memorizes" your training photos. In testing, it yields 99% accuracy, but in real-world conditions, it confuses the simplest objects.
- Greenhouse/Laboratory Tests. If you train the system exclusively on high-quality studio photos, it will prove helpless under real lighting, glare, or partial object occlusion.
- The Metric Trap. If your dataset contains 95% healthy scans and only 5% with pathologies, a model that always predicts "healthy" will have 95% accuracy. But it will be completely useless! Use Precision, Recall, and F1-Score metrics to evaluate real quality.
A confusion matrix helps visualize which exact classes the model confuses with one another. For instance, a system might distinguish most products well, but regularly stumble between two visually similar categories.
In addition to metrics, it's important to look at the false predictions themselves. These may indicate ambiguous labels, underrepresentation of certain shooting conditions, or similarity between categories. If the problem is data-related, changing the algorithm alone may not fix it.
How to Improve Classification Performance
Transfer learning allows you to adapt a pre-trained model to a specific task. Data augmentation – for example, moderate changes in scale, cropping, or lighting – helps the model work better with the natural variability of images, as long as these transformations are consistent with real-world usage.
If the dataset is unbalanced, class weighting or other methods for working with rare categories can be used. Before deploying the model, you should test it on an independent sample, and after it is run, you should monitor its performance. Changes in image quality, the appearance of new categories, or other differences between the training data and the real stream can gradually degrade the results.
Image classification is used in many areas, and in each case, you should choose an algorithm based on the specific task, available resources, and the cost of error. And a high-quality, consistently annotated dataset helps make the model’s results more reliable.
FAQ
What is the difference between image classification and object detection?
Image classification determines which class an image belongs to as a whole. Object detection locates individual objects within an image and determines their boundaries. For example, a classifier can determine that a photo contains a car, whereas a detector will find all cars and draw bounding boxes around them.
How many images are needed to train an image classification model?
Requirements depend on task complexity, class count, image diversity, and whether a pre-trained model is used. Instead of collecting a massive dataset immediately, it is better to start with a representative sample and track how model quality improves as data volume increases.
When should an image classification model be retrained?
Retraining may be necessary when the survey conditions change, new categories appear, or the results on real data deteriorate. Regular evaluation of predictions helps to detect such changes in time and determine whether it is enough to update the dataset or whether the model itself needs to be adapted.
How can image classification reduce business costs?
Automatic classification helps to process large sets of images without manually sorting each file. It is used for product categorization, product quality control, document sorting, and pre-analysis of medical images. The actual savings depend on the accuracy of the model, the cost of computing, and the number of cases that still need human verification.